I Gave History One Star: Building an AI YouTube Channel
I built One Star Review — an AI YouTube channel where a luxury influencer leaves one-star reviews for the worst travel experiences in history. Two burned budgets, two pivots, one face-filter arms race, and a 3½-minute Hindenburg film later, here's the honest production diary.
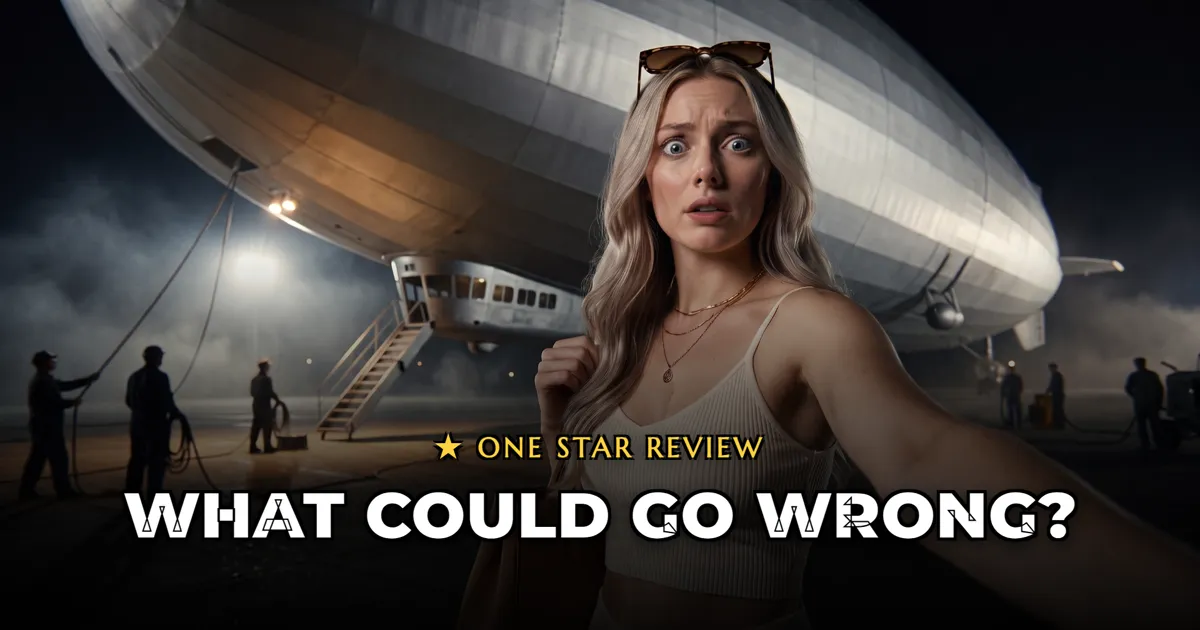
For the past two weeks I’ve been running a YouTube channel where nobody involved is real. The host is an AI-generated British luxury influencer named Allegra. Her only companion is David, a voice-only AI assistant who feeds her actual history while she complains about the amenities. The channel is called One Star Review, and its thesis fits in one line: the worst travel reviews in history. Allegra gives the Hindenburg one star because the smoking lounge had a waiting list. David gently notes the ship is full of hydrogen. That’s the whole engine.
This post is the production diary: where the idea came from, the two times I face-planted, what the pipeline actually looks like, the surprisingly grimy world of Seedance resellers, and what it all costs.
The inspiration: Chloe vs History
If you watch any history content on YouTube, the algorithm has probably shown you Chloe vs History — a channel where a beautiful twenty-something American girl time-travels into ancient Rome, Pompeii, and onto the Titanic, vlogging the whole way. It’s gone properly viral. Chloe is not real. The whole thing — host included — is AI-generated by one guy in the English countryside, who cheerfully admitted as much when Sky News came knocking. The production recipe (image model for keyframes, Seedance for video, an LLM for scripts) has since been dissected in public teardowns.
I found the format genuinely clever, and I wanted my own angle rather than a clone. My differentiator was the review conceit: Allegra doesn’t just visit history, she reviews it like a holiday destination — amenities, service, signal, star ratings, “is there a pool?” — and she rates honestly, so genuinely awe-inspiring history can claw its way up from half a star. The second differentiator was making it a two-hander: all the real facts flow through David, so the history stays accurate while Allegra supplies the feelings. Oblivious diva versus patient genius.
First takes: the disappointing part
The original plan was long-form — six-minute episodes at Göbekli Tepe, Apollo 11, Titan. I wrote five full scripts, built character bibles, and started rendering.
In roughly 24 hours I burned through the entire budget: ~168 image generations and ~65 video renders, across three different render pipelines, with zero finished episodes. Not one. I wrote a proper blameless postmortem afterwards, and the failure pattern is almost embarrassingly legible in hindsight:
- Identity drift. The image model exposes no seed, so Allegra’s face rested entirely on one reference image plus prose. Her face and hair shifted scene to scene — and instead of locking the reference, I re-rolled it three times (brunette → blonde → northern). Every keyframe prompt pasted the appearance block “verbatim”… at a moving target.
- Setting drift. Ask a model for a Neolithic settlement and it hands you generic sun-baked Egyptian ruins. Text negatives could not out-shout the model’s “ancient site = ruins” prior.
- Five episodes in parallel. Each one restarted the expensive first-scene R&D loop instead of amortizing it across one finished piece. I also swapped render pipelines twice mid-project. R&D and production ran simultaneously, and nothing forced the question “is one episode actually done?” before the next began.
- Contact sheets existed but weren’t gates. I generated them to review the damage after paying, not to approve spend before it.
The writing was never the bottleneck. The economics and the consistency tooling were.
Pivot two: a younger, louder Allegra
The first pivot (long-form → short vertical single-joke pieces) fixed the economics and shipped a couple dozen shorts. But it left a strategic problem: I was still operating in Chloe’s lane — attractive AI woman visits history and reacts — a niche already normalized at a very high visual-quality bar. A cheaper, lower-fidelity version of that gets judged as derivative before the writing ever lands.
So the second pivot changed the character and the format at once. Allegra got rebooted from a contemptuous posh snob into someone younger and far more energetic — a theatrical diva who plays mid-20s, narrates her feelings in real time, and can’t help getting swept up (“wait, wait— David, what IS that?”). She also got a real voice: I used ElevenLabs Voice Design to audition candidate voices against actual script lines and locked a “theatrical diva” identity that now belongs to the character.
The format became complaint comedy: card-first, joke-first, and — crucially — resilient to imperfect AI video. Every short opens on a branded review card that’s legible in half a second. Allegra complains in hospitality language, David corrects her, and the correction is the history. One fact per joke. And the rule that saved the budget: no AI face shot longer than 2.5 seconds unless it’s excellent. The framing device — “recovered from Allegra’s complaint logs” — makes mixed media and visual imperfection read as intentional rather than cheap.
We are not “Chloe but reviews ruins.” We are the complaint desk of history.
The pipeline
Everything below runs out of a git repo, orchestrated by Claude Code, with small Python tools wrapping each provider:
- Scripts — written first, as text, because text is free. Shot lists and card copy get locked before a single image is generated.
- Keyframes — Nano Banana Pro (Gemini image gen), always conditioned on Allegra’s locked reference image plus a verbatim appearance block, plus real reference photos of the location and a hard-negative anachronism list. Pre-viz grids come first as a cheap spend gate; I view every keyframe before its clip is rendered.
- Video — Seedance, image-to-video, always with native audio. Dialogue is written into the generation prompt so Allegra’s lip-synced performance comes out of the model already speaking.
- Voice — the clever bit. Allegra’s voice-over lines are plain ElevenLabs TTS. But her on-camera lines come out of Seedance with a random voice — so they go through ElevenLabs Voice Changer (speech-to-speech), which swaps the timbre to her locked voice while preserving the timing and intonation. Lip-sync survives. David is a stock ElevenLabs voice, phone-EQ’d in the mix.
- Assembly — Remotion, which I’d already used for lyric videos. The card system (review card, fact-check overlay, verdict card, star flickers) is all React components; clips are props. Two-pass loudnorm to −14 LUFS via ffmpeg.
- Distribution — a self-hosted Postiz instance schedules to YouTube, TikTok, Instagram, Threads, and X.
Each expensive step is protected by a cheap one in front of it. That discipline is the actual lesson from the postmortem, and it’s now baked in hard enough that I extracted the whole thing into a blank template repo for future channels.
If this pipeline shape looks familiar, it’s because I keep building it: FableCast did text→image→narration for children’s books, and Slop Machine generalized it for illustrated stories. This is the same beast with a video model bolted on and a much meaner accountant.
The Seedance provider safari
Here’s where it gets grubby. The complaint-comedy format needs one thing the budget path can’t do: Seedance 2.0 reference-to-video with a photoreal character reference — feed it Allegra’s portrait and a location still, get back a clip of her in that place, speaking, with native audio.
The catch: Seedance 2.0 ships with a face filter that blocks photographs of real people, and BytePlus ModelArk — ByteDance’s own enterprise API, my most reliable vendor — enforces it strictly enough that it rejects Allegra too, even though she’s fully synthetic and the most legally defensible character reference imaginable. So the first-party door is closed for character work on 2.0.
That pushes you into the reseller tier, and the reseller tier is a swamp. I did a proper survey, and the honest summary is: there is no reputationally clean pay-per-use Seedance host. Vanished prepaid credits with unresponsive billing support are endemic across the field’s Trustpilot pages. One host had a 2.5/5 rating full of “credits gone, sorry, no refund” stories and got classified as throwaway-free-trial-only. Others were too small to have a record at all, which is its own kind of warning. fal.ai came out as the most production-proven of the bunch — real engineering org, best docs — and even their reviews are full of billing horror stories.
So the strategy became guardrails rather than trust: never hold a meaningful prepaid balance, spend caps on everything, validate any new host with a single ~$1 clip before committing, and wrap every provider behind my own CLI tool so switching hosts is a flag, not a rewrite. Right now character clips run on a small reseller that validated cleanly (likeness, wardrobe, native audio), with fal as the tested fallback for scale. ModelArk stays the backbone for everything else — Seedance 1.5 Pro character clips with native audio, and 2.0 for B-roll, where no faces are involved and the filter has nothing to object to.
What it costs
Concrete numbers, because AI-video posts never give them:
- A 5-second 720p character clip (Seedance 2.0, reference-to-video, native audio): about $0.90.
- A 15-second 1080p multi-shot roll for the long-form film: about $6.70 per roll.
- The entire six-short Hindenburg slate — six finished vertical videos with character clips, B-roll, TTS, music, and mastering — cost about $11 in video generation.
- The 3½-minute 16:9 flagship film burned roughly 4,400 credits ≈ $65 in character rolls (nine scenes, some retakes, plus two orphaned renders I paid for twice when a timed-out task charged server-side — recovered later via console task IDs).
Add the ElevenLabs subscription, pennies of B-roll on ModelArk, and the one-time cost of the failed long-form launch, and the whole channel to date has cost less than a single day of a real camera crew. The failed launch remains the most expensive line item — which is exactly the point of all those gates.
What’s next
The Hindenburg slate — six shorts plus the film — is finished and heading into distribution, where the mini-test discipline continues: measure retention and comments before scaling to the full 12-topic slate. The 16:9 film is the format bet: vertical shorts are the validation vehicle, not the ceiling.
And there’s a second channel brewing: 生成ちゃん (Sei-chan), a Japanese-first sister project. Different engine, same DNA: an openly-AI Japanese reporter is deployed into historical moments and reviews them against Japanese common sense as the spec — bath etiquette, queue discipline, もったいない — filing calm 歴史バグ報告 (history bug reports) when the past fails the spec, and losing gracefully when it wins. Japan’s synthetic-host culture means an AI reporter is a native genre there, not a gimmick. Her system stamps 「※諸説あります」 over her own pop-history claims, and once per episode a staff voice delivers the verdict: it’s not a bug, it’s the spec. The pilot slate is written; production starts on the template extracted from everything above.
The film
The flagship: Allegra spends a 1936 Atlantic crossing aboard the Hindenburg — the year before Lakehurst — being slowly won over by the impossible glamour of it, while the audience knows something she doesn’t.
- Watch: I Flew on the Hindenburg 🔥. In 1936
- Channel: One Star Review
Five stars for the view. One star for the hydrogen.
related entriesshared tags